swap write를 제출했는데 RSS가 바로 줄지 않는 것은 이상한 일이 아닙니다. backing을 예약하는 시점, present PTE를 바꾸는 시점, storage I/O를 완료하는 시점, folio를 allocator에 돌려주는 시점이 다르기 때문입니다. 이 글은 v6.12의 ordinary swap-backed anon 경로를 기준으로 설명합니다.
Slot cache와 data cache는 다른 것입니다
folio_alloc_swap()은 사용할 swap entry를 얻습니다. ordinary 작은 folio에서는 per-CPU swap slot cache를 이용할 수 있고, 필요하면 get_swap_pages()로 area에서 slot을 확보합니다. 여기서 SWAP_BATCH=64는 slot allocation을 모으는 크기이지 data를 64 page씩 쓰거나 읽으라는 뜻이 아닙니다.
v6.12의 order-0 slot-cache allocation은 cache->alloc_lock mutex로 보호합니다. refill이 sleep할 수 있으므로 이 per-CPU 자료구조의 접근을 무조건 preemption-disabled 구간이라고 가정하면 안 됩니다. allocation 경로는 반환 slot 배열을 다루지 않아 free_lock과도 구분됩니다. LRU operation batch의 local lock 규칙을 slot cache에 그대로 적용할 수 없는 이유입니다.
swap cache는 resident data folio를 찾는 구조입니다. slot을 확보했더라도 cache metadata allocation이나 등록은 실패할 수 있습니다. add_to_swap()은 이런 실패에 slot accounting을 되돌려야 하며, 성공한 folio를 dirty로 표시해 새 backing에 내용을 보존해야 함을 분명히 합니다. 이 dirty는 I/O가 벌써 시작되었다는 표시가 아닙니다.
Cache 등록에는 folio와 자료구조 양쪽 변화가 있습니다
v6.12의 add_to_swap_cache()는 적절한 swapper address space의 XArray를 준비하고 folio에 cache-held reference를 추가합니다. PG_swapcache와 entry metadata를 설정하며 각 subpage에 대응하는 index 관계를 유지합니다. XArray node 확보는 lock 안에서 무조건 성공한다고 가정할 수 없으므로 오류와 재시도·rollback이 필요합니다.
등록 실패 시 v6.12의 helper는 cache flag와 추가 reference를 되돌리고 caller가 slot을 반환합니다. 이때 folio->swap 필드를 0으로 지우지는 않으므로, 그 필드에 값이 남았다는 사실만으로 유효한 cache membership을 판정하면 안 됩니다. user mapping이 유지하는 reference와 cache가 추가한 reference를 구분해야 이 정리가 맞습니다. 이 설명을 v6.18의 per-cluster swap table에 그대로 대입할 수는 없습니다.
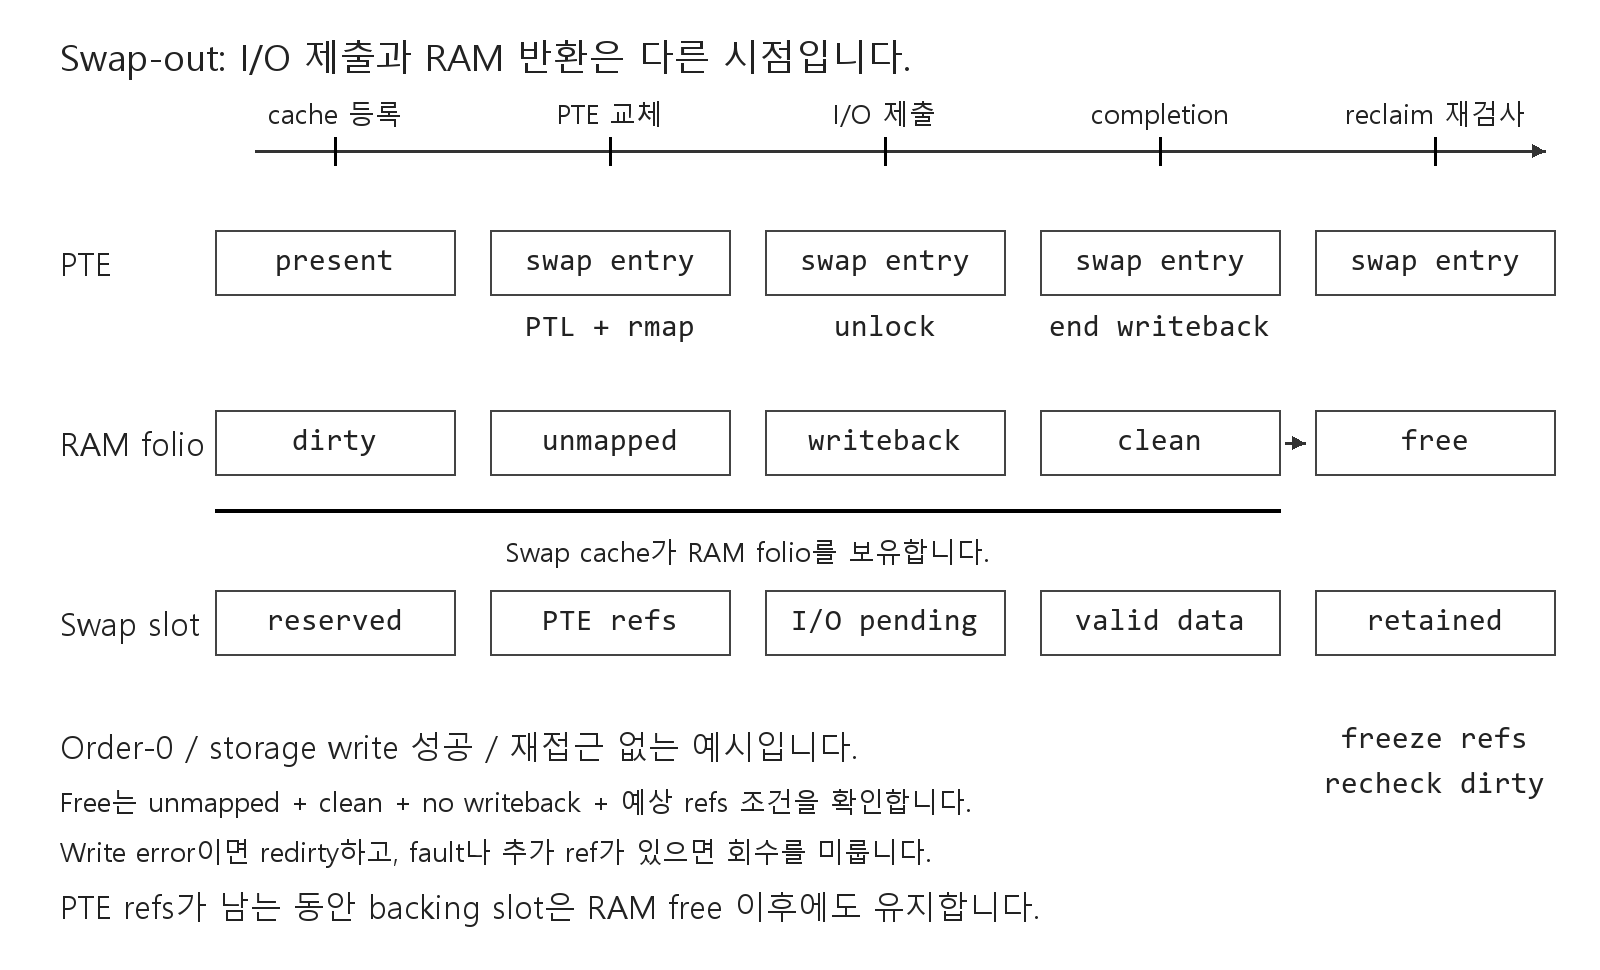
Dirty clear 뒤 backend가 writeback을 시작합니다
unmap이 완료되고 dirty인 folio는 reclaim의 pageout()을 통해 swap write 경로로 갑니다. folio_mapping()이 반환하는 swapper operation의 writepage callback은 swap_writepage()입니다. pageout()은 dirty를 I/O용으로 정리하고 reclaim 표시를 남긴 뒤 callback을 호출합니다. PG_writeback을 실제로 시작하는 책임은 하위 backend에 있습니다.
swap_writepage()를 호출했다고 항상 disk write를 제출하는 것은 아닙니다. 더 이상 slot을 유지할 필요가 없어 cache를 정리할 수 있거나, zero-filled 내용 또는 compressed backing으로 처리하는 branch도 있습니다. 'writepage 호출 횟수 = physical disk write 수'라는 등식은 성립하지 않습니다.
storage write가 필요하면 backend에 따라 filesystem operation을 사용하거나 block I/O를 구성합니다. block 경로에서는 bio를 준비하고 folio를 writeback 상태로 전환한 뒤 unlock하여 I/O를 제출합니다. filesystem-mediated batch의 SWAP_CLUSTER_MAX는 slot allocation batch나 readahead window와 다른 정책 단위입니다.
Completion은 다시 reclaim할 기회입니다
비동기 I/O 동안에는 folio lock이 풀려 있어도 PG_writeback이 내용을 보호하는 protocol의 일부입니다. 이때 RAM을 다른 data로 재사용하면 I/O가 엉뚱한 내용을 읽을 수 있으므로 free할 수 없습니다. write error가 나면 redirty와 오류 처리를 거쳐 내용을 보존해야 합니다.
completion은 writeback 상태를 끝내고 필요한 경우 inactive-tail rotation을 요청합니다. 모든 folio가 무조건 즉시 회수되는 것은 아닙니다. callback 뒤 dirty·writeback과 lock 상태를 다시 검사해야 하며, 그 사이 fault가 같은 cache folio를 재사용할 수도 있습니다. PAGE_SUCCESS도 보통 제출 성공이지 I/O 완료나 final free가 아닙니다.
Cache에서 떼는 순간에도 refcount를 확인합니다
다음 reclaim에서 clean·unmapped·non-writeback 상태인 folio는 __remove_mapping()으로 cache 연결을 끊을 수 있습니다. v6.12에서는 XArray lock과 folio lock을 사용하고, 예상 참조 수인 1 + folio_nr_pages(folio)와 정확히 일치할 때 folio_ref_freeze()로 원자적으로 0으로 바꿉니다. 1은 reclaim isolation이 가진 참조이고 나머지는 cache의 base-page별 보유분입니다. 추가 kernel reference나 pin으로 count가 더 크면 freeze가 실패하므로 folio를 유지합니다.
freeze 뒤 dirty를 재검사하여 뒤늦은 수정이 보이면 unfreeze하고 보존합니다. cache entry는 빈 값이나 working-set shadow로 바뀌고 PG_swapcache·slot cache accounting을 정리합니다. 그 뒤 caller가 folio를 bulk free해야 allocator가 RAM을 재사용할 수 있습니다. cache 삭제 자체가 final folio free는 아닙니다.
RAM은 유지하고 slot을 반환하는 경우
resident folio를 계속 쓰더라도 swap PTE가 더 이상 없고 writeback 같은 제약을 만족하면 folio_free_swap()으로 backing/cache를 정리할 수 있습니다. 이때 cache를 떼면 folio를 dirty로 표시하여 backing 없이 남은 내용의 보존 책임을 유지합니다. present mapping이 folio를 살려 두므로 RAM은 그대로일 수 있습니다.
folio_swapped()가 참이면 아직 slot을 참조하는 swap PTE가 있는 방향이므로 자유롭게 backing을 버릴 수 없습니다. writeback 중이거나 hibernation storage 보존 같은 특별 조건에서도 제거를 제한합니다. 함수 이름에 free가 있다고 모든 entry 참조와 memory를 한 번에 버린다고 해석해서는 안 됩니다.
Slot allocation 실패와 cache 등록 실패를 분리합니다
v6.0에서는 folio_alloc_swap()이 swp_entry_t를 반환하고, add_to_swap()은 bool을 반환합니다. 앞 함수의 0 entry와 뒤 함수의 false는 서로 다른 단계의 실패입니다. 아래는 두 함수와 cache 등록의 전체 정의입니다. official tag code의 notice와 GPL-2.0을 유지했습니다.
// SPDX-License-Identifier: GPL-2.0
/*
 * Manage cache of swap slots to be used for and returned from
 * swap.
 *
 * Copyright(c) 2016 Intel Corporation.
 *
 * Author: Tim Chen <tim.c.chen@linux.intel.com>
 *
 * We allocate the swap slots from the global pool and put
 * it into local per cpu caches.  This has the advantage
 * of no needing to acquire the swap_info lock every time
 * we need a new slot.
 *
 * There is also opportunity to simply return the slot
 * to local caches without needing to acquire swap_info
 * lock.  We do not reuse the returned slots directly but
 * move them back to the global pool in a batch.  This
 * allows the slots to coalesce and reduce fragmentation.
 *
 * The swap entry allocated is marked with SWAP_HAS_CACHE
 * flag in map_count that prevents it from being allocated
 * again from the global pool.
 *
 * The swap slots cache is protected by a mutex instead of
 * a spin lock as when we search for slots with scan_swap_map,
 * we can possibly sleep.
 */

/*
 * Official Linux v6.0: mm/swap_slots.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/swap_slots.c#L302
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

swp_entry_t folio_alloc_swap(struct folio *folio)
{
	swp_entry_t entry;
	struct swap_slots_cache *cache;

	entry.val = 0;

	if (folio_test_large(folio)) {
		if (IS_ENABLED(CONFIG_THP_SWAP) && arch_thp_swp_supported())
			get_swap_pages(1, &entry, folio_nr_pages(folio));
		goto out;
	}

	/*
	 * Preemption is allowed here, because we may sleep
	 * in refill_swap_slots_cache().  But it is safe, because
	 * accesses to the per-CPU data structure are protected by the
	 * mutex cache->alloc_lock.
	 *
	 * The alloc path here does not touch cache->slots_ret
	 * so cache->free_lock is not taken.
	 */
	cache = raw_cpu_ptr(&swp_slots);

	if (likely(check_cache_active() && cache->slots)) {
		mutex_lock(&cache->alloc_lock);
		if (cache->slots) {
repeat:
			if (cache->nr) {
				entry = cache->slots[cache->cur];
				cache->slots[cache->cur++].val = 0;
				cache->nr--;
			} else if (refill_swap_slots_cache(cache)) {
				goto repeat;
			}
		}
		mutex_unlock(&cache->alloc_lock);
		if (entry.val)
			goto out;
	}

	get_swap_pages(1, &entry, 1);
out:
	if (mem_cgroup_try_charge_swap(folio, entry)) {
		put_swap_page(&folio->page, entry);
		entry.val = 0;
	}
	return entry;
}
// SPDX-License-Identifier: GPL-2.0
/*
 *  linux/mm/swap_state.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 *
 *  Rewritten to use page cache, (C) 1998 Stephen Tweedie
 */

/*
 * Official Linux v6.0: mm/swap_state.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/swap_state.c#L174
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

bool add_to_swap(struct folio *folio)
{
	swp_entry_t entry;
	int err;

	VM_BUG_ON_FOLIO(!folio_test_locked(folio), folio);
	VM_BUG_ON_FOLIO(!folio_test_uptodate(folio), folio);

	entry = folio_alloc_swap(folio);
	if (!entry.val)
		return false;

	/*
	 * XArray node allocations from PF_MEMALLOC contexts could
	 * completely exhaust the page allocator. __GFP_NOMEMALLOC
	 * stops emergency reserves from being allocated.
	 *
	 * TODO: this could cause a theoretical memory reclaim
	 * deadlock in the swap out path.
	 */
	/*
	 * Add it to the swap cache.
	 */
	err = add_to_swap_cache(&folio->page, entry,
			__GFP_HIGH|__GFP_NOMEMALLOC|__GFP_NOWARN, NULL);
	if (err)
		/*
		 * add_to_swap_cache() doesn't return -EEXIST, so we can safely
		 * clear SWAP_HAS_CACHE flag.
		 */
		goto fail;
	/*
	 * Normally the folio will be dirtied in unmap because its
	 * pte should be dirty. A special case is MADV_FREE page. The
	 * page's pte could have dirty bit cleared but the folio's
	 * SwapBacked flag is still set because clearing the dirty bit
	 * and SwapBacked flag has no lock protected. For such folio,
	 * unmap will not set dirty bit for it, so folio reclaim will
	 * not write the folio out. This can cause data corruption when
	 * the folio is swapped in later. Always setting the dirty flag
	 * for the folio solves the problem.
	 */
	folio_mark_dirty(folio);

	return true;

fail:
	put_swap_page(&folio->page, entry);
	return false;
}
// SPDX-License-Identifier: GPL-2.0
/*
 *  linux/mm/swap_state.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 *
 *  Rewritten to use page cache, (C) 1998 Stephen Tweedie
 */

/*
 * Official Linux v6.0: mm/swap_state.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/swap_state.c#L88
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

int add_to_swap_cache(struct page *page, swp_entry_t entry,
			gfp_t gfp, void **shadowp)
{
	struct address_space *address_space = swap_address_space(entry);
	pgoff_t idx = swp_offset(entry);
	XA_STATE_ORDER(xas, &address_space->i_pages, idx, compound_order(page));
	unsigned long i, nr = thp_nr_pages(page);
	void *old;

	VM_BUG_ON_PAGE(!PageLocked(page), page);
	VM_BUG_ON_PAGE(PageSwapCache(page), page);
	VM_BUG_ON_PAGE(!PageSwapBacked(page), page);

	page_ref_add(page, nr);
	SetPageSwapCache(page);

	do {
		xas_lock_irq(&xas);
		xas_create_range(&xas);
		if (xas_error(&xas))
			goto unlock;
		for (i = 0; i < nr; i++) {
			VM_BUG_ON_PAGE(xas.xa_index != idx + i, page);
			old = xas_load(&xas);
			if (xa_is_value(old)) {
				if (shadowp)
					*shadowp = old;
			}
			set_page_private(page + i, entry.val + i);
			xas_store(&xas, page);
			xas_next(&xas);
		}
		address_space->nrpages += nr;
		__mod_node_page_state(page_pgdat(page), NR_FILE_PAGES, nr);
		__mod_lruvec_page_state(page, NR_SWAPCACHE, nr);
unlock:
		xas_unlock_irq(&xas);
	} while (xas_nomem(&xas, gfp));

	if (!xas_error(&xas))
		return 0;

	ClearPageSwapCache(page);
	page_ref_sub(page, nr);
	return xas_error(&xas);
}
large folio는 THP swap과 architecture 지원이 있을 때 연속한 base-page 수만큼 별도 배정을 시도합니다. 작은 folio는 mutex로 보호한 per-CPU slot cache에서 하나를 꺼내고, 비었으면 refill 후 다시 봅니다. cache가 비활성이거나 slot을 얻지 못했다면 get_swap_pages()로 fallback합니다. 마지막 memcg charge가 실패해도 이미 얻은 slot을 반환해야 합니다.
cache 등록은 XA_STATE_ORDER로 범위를 준비하고 base-page 수만큼 reference를 추가합니다. XArray lock 안에서 range 생성이 실패하면 unlock한 뒤 xas_nomem()으로 memory 확보·재시도를 시도합니다. 끝내 실패하면 cache flag와 추가 reference를 되돌립니다. 이 helper는 -EEXIST를 반환하는 reservation 경쟁용 helper가 아니므로 add_to_swap()은 자신의 배정 entry의 cache 보유 상태를 안전하게 정리할 수 있습니다.
성공한 folio를 항상 dirty로 만드는 데에는 MADV_FREE 경쟁도 포함됩니다. PTE dirty가 이미 clear되었지만 swap-backed flag가 아직 남은 순간에는 뒤의 unmap만 믿고 dirty 전파를 기대할 수 없습니다. 내용이 있는 folio에 새 backing을 배정한 이상 writeout 필요성을 잃지 않아야 합니다.
v6.12는 같은 boolean 예약 wrapper를 유지하되 cache 등록 인자는 folio이고 entry는 folio->swap에 둡니다. subpage의 page_private()를 채우는 v6.0 code와 구별해 보십시오.
// SPDX-License-Identifier: GPL-2.0
/*
 *  linux/mm/swap_state.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 *
 *  Rewritten to use page cache, (C) 1998 Stephen Tweedie
 */

/*
 * Official Linux v6.12: mm/swap_state.c
 * https://github.com/torvalds/linux/blob/v6.12/mm/swap_state.c#L180
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

bool add_to_swap(struct folio *folio)
{
	swp_entry_t entry;
	int err;

	VM_BUG_ON_FOLIO(!folio_test_locked(folio), folio);
	VM_BUG_ON_FOLIO(!folio_test_uptodate(folio), folio);

	entry = folio_alloc_swap(folio);
	if (!entry.val)
		return false;

	/*
	 * XArray node allocations from PF_MEMALLOC contexts could
	 * completely exhaust the page allocator. __GFP_NOMEMALLOC
	 * stops emergency reserves from being allocated.
	 *
	 * TODO: this could cause a theoretical memory reclaim
	 * deadlock in the swap out path.
	 */
	/*
	 * Add it to the swap cache.
	 */
	err = add_to_swap_cache(folio, entry,
			__GFP_HIGH|__GFP_NOMEMALLOC|__GFP_NOWARN, NULL);
	if (err)
		/*
		 * add_to_swap_cache() doesn't return -EEXIST, so we can safely
		 * clear SWAP_HAS_CACHE flag.
		 */
		goto fail;
	/*
	 * Normally the folio will be dirtied in unmap because its
	 * pte should be dirty. A special case is MADV_FREE page. The
	 * page's pte could have dirty bit cleared but the folio's
	 * SwapBacked flag is still set because clearing the dirty bit
	 * and SwapBacked flag has no lock protected. For such folio,
	 * unmap will not set dirty bit for it, so folio reclaim will
	 * not write the folio out. This can cause data corruption when
	 * the folio is swapped in later. Always setting the dirty flag
	 * for the folio solves the problem.
	 */
	folio_mark_dirty(folio);

	return true;

fail:
	put_swap_folio(folio, entry);
	return false;
}
// SPDX-License-Identifier: GPL-2.0
/*
 *  linux/mm/swap_state.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 *
 *  Rewritten to use page cache, (C) 1998 Stephen Tweedie
 */

/*
 * Official Linux v6.12: mm/swap_state.c
 * https://github.com/torvalds/linux/blob/v6.12/mm/swap_state.c#L90
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

int add_to_swap_cache(struct folio *folio, swp_entry_t entry,
			gfp_t gfp, void **shadowp)
{
	struct address_space *address_space = swap_address_space(entry);
	pgoff_t idx = swap_cache_index(entry);
	XA_STATE_ORDER(xas, &address_space->i_pages, idx, folio_order(folio));
	unsigned long i, nr = folio_nr_pages(folio);
	void *old;

	xas_set_update(&xas, workingset_update_node);

	VM_BUG_ON_FOLIO(!folio_test_locked(folio), folio);
	VM_BUG_ON_FOLIO(folio_test_swapcache(folio), folio);
	VM_BUG_ON_FOLIO(!folio_test_swapbacked(folio), folio);

	folio_ref_add(folio, nr);
	folio_set_swapcache(folio);
	folio->swap = entry;

	do {
		xas_lock_irq(&xas);
		xas_create_range(&xas);
		if (xas_error(&xas))
			goto unlock;
		for (i = 0; i < nr; i++) {
			VM_BUG_ON_FOLIO(xas.xa_index != idx + i, folio);
			if (shadowp) {
				old = xas_load(&xas);
				if (xa_is_value(old))
					*shadowp = old;
			}
			xas_store(&xas, folio);
			xas_next(&xas);
		}
		address_space->nrpages += nr;
		__node_stat_mod_folio(folio, NR_FILE_PAGES, nr);
		__lruvec_stat_mod_folio(folio, NR_SWAPCACHE, nr);
unlock:
		xas_unlock_irq(&xas);
	} while (xas_nomem(&xas, gfp));

	if (!xas_error(&xas))
		return 0;

	folio_clear_swapcache(folio);
	folio_ref_sub(folio, nr);
	return xas_error(&xas);
}
v6.18에서는 아래 하나의 folio_alloc_swap(folio, gfp)가 slot 배정과 swap table 연결을 수행합니다. 성공은 0, THP swap이 꺼진 large allocation은 -EAGAIN, cluster보다 큰 요청은 -EINVAL, 공간·charge 실패는 -ENOMEM입니다. local lock을 쓰는 per-CPU cluster 경로를 고전 slot-cache mutex 경로와 섞지 않습니다.
// SPDX-License-Identifier: GPL-2.0-only
/*
 *  linux/mm/swapfile.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 */

/*
 * Official Linux v6.18: mm/swapfile.c
 * https://github.com/torvalds/linux/blob/v6.18/mm/swapfile.c#L1408
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

int folio_alloc_swap(struct folio *folio, gfp_t gfp)
{
	unsigned int order = folio_order(folio);
	unsigned int size = 1 << order;
	swp_entry_t entry = {};

	VM_BUG_ON_FOLIO(!folio_test_locked(folio), folio);
	VM_BUG_ON_FOLIO(!folio_test_uptodate(folio), folio);

	if (order) {
		/*
		 * Reject large allocation when THP_SWAP is disabled,
		 * the caller should split the folio and try again.
		 */
		if (!IS_ENABLED(CONFIG_THP_SWAP))
			return -EAGAIN;

		/*
		 * Allocation size should never exceed cluster size
		 * (HPAGE_PMD_SIZE).
		 */
		if (size > SWAPFILE_CLUSTER) {
			VM_WARN_ON_ONCE(1);
			return -EINVAL;
		}
	}

	local_lock(&percpu_swap_cluster.lock);
	if (!swap_alloc_fast(&entry, order))
		swap_alloc_slow(&entry, order);
	local_unlock(&percpu_swap_cluster.lock);

	/* Need to call this even if allocation failed, for MEMCG_SWAP_FAIL. */
	if (mem_cgroup_try_charge_swap(folio, entry))
		goto out_free;

	if (!entry.val)
		return -ENOMEM;

	swap_cache_add_folio(folio, entry, NULL);

	return 0;

out_free:
	put_swap_folio(folio, entry);
	return -ENOMEM;
}
Write 제출과 completion의 전체 경로
고전 v6.0 pageout()은 caller의 freeable 검사, mapping·private buffer 처리, dirty clear와 callback을 함께 보여 줍니다. nr_to_write=SWAP_CLUSTER_MAX는 writeback budget이며 실제로 32 page의 disk write가 발생했다는 결과가 아닙니다. writepage가 AOP_WRITEPAGE_ACTIVATE를 반환하면 reclaim 표시를 지우고 PAGE_ACTIVATE를 반환합니다. 음수 오류를 기록하는 것과 backend가 folio를 unlock했는지도 읽어야 합니다.
// SPDX-License-Identifier: GPL-2.0
/*
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *
 *  Swap reorganised 29.12.95, Stephen Tweedie.
 *  kswapd added: 7.1.96  sct
 *  Removed kswapd_ctl limits, and swap out as many pages as needed
 *  to bring the system back to freepages.high: 2.4.97, Rik van Riel.
 *  Zone aware kswapd started 02/00, Kanoj Sarcar (kanoj@sgi.com).
 *  Multiqueue VM started 5.8.00, Rik van Riel.
 */

#define pr_fmt(fmt) KBUILD_MODNAME ": " fmt

/*
 * Official Linux v6.0: mm/vmscan.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/vmscan.c#L1215
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

static pageout_t pageout(struct folio *folio, struct address_space *mapping,
			 struct swap_iocb **plug)
{
	/*
	 * If the folio is dirty, only perform writeback if that write
	 * will be non-blocking.  To prevent this allocation from being
	 * stalled by pagecache activity.  But note that there may be
	 * stalls if we need to run get_block().  We could test
	 * PagePrivate for that.
	 *
	 * If this process is currently in __generic_file_write_iter() against
	 * this folio's queue, we can perform writeback even if that
	 * will block.
	 *
	 * If the folio is swapcache, write it back even if that would
	 * block, for some throttling. This happens by accident, because
	 * swap_backing_dev_info is bust: it doesn't reflect the
	 * congestion state of the swapdevs.  Easy to fix, if needed.
	 */
	if (!is_page_cache_freeable(folio))
		return PAGE_KEEP;
	if (!mapping) {
		/*
		 * Some data journaling orphaned folios can have
		 * folio->mapping == NULL while being dirty with clean buffers.
		 */
		if (folio_test_private(folio)) {
			if (try_to_free_buffers(folio)) {
				folio_clear_dirty(folio);
				pr_info("%s: orphaned folio\n", __func__);
				return PAGE_CLEAN;
			}
		}
		return PAGE_KEEP;
	}
	if (mapping->a_ops->writepage == NULL)
		return PAGE_ACTIVATE;

	if (folio_clear_dirty_for_io(folio)) {
		int res;
		struct writeback_control wbc = {
			.sync_mode = WB_SYNC_NONE,
			.nr_to_write = SWAP_CLUSTER_MAX,
			.range_start = 0,
			.range_end = LLONG_MAX,
			.for_reclaim = 1,
			.swap_plug = plug,
		};

		folio_set_reclaim(folio);
		res = mapping->a_ops->writepage(&folio->page, &wbc);
		if (res < 0)
			handle_write_error(mapping, folio, res);
		if (res == AOP_WRITEPAGE_ACTIVATE) {
			folio_clear_reclaim(folio);
			return PAGE_ACTIVATE;
		}

		if (!folio_test_writeback(folio)) {
			/* synchronous write or broken a_ops? */
			folio_clear_reclaim(folio);
		}
		trace_mm_vmscan_write_folio(folio);
		node_stat_add_folio(folio, NR_VMSCAN_WRITE);
		return PAGE_SUCCESS;
	}

	return PAGE_CLEAN;
}
// SPDX-License-Identifier: GPL-2.0
/*
 *  linux/mm/page_io.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *
 *  Swap reorganised 29.12.95,
 *  Asynchronous swapping added 30.12.95. Stephen Tweedie
 *  Removed race in async swapping. 14.4.1996. Bruno Haible
 *  Add swap of shared pages through the page cache. 20.2.1998. Stephen Tweedie
 *  Always use brw_page, life becomes simpler. 12 May 1998 Eric Biederman
 */

/*
 * Official Linux v6.0: mm/page_io.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/page_io.c#L181
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

int swap_writepage(struct page *page, struct writeback_control *wbc)
{
	int ret = 0;

	if (try_to_free_swap(page)) {
		unlock_page(page);
		goto out;
	}
	/*
	 * Arch code may have to preserve more data than just the page
	 * contents, e.g. memory tags.
	 */
	ret = arch_prepare_to_swap(page);
	if (ret) {
		set_page_dirty(page);
		unlock_page(page);
		goto out;
	}
	if (frontswap_store(page) == 0) {
		set_page_writeback(page);
		unlock_page(page);
		end_page_writeback(page);
		goto out;
	}
	ret = __swap_writepage(page, wbc, end_swap_bio_write);
out:
	return ret;
}
// SPDX-License-Identifier: GPL-2.0
/*
 *  linux/mm/page_io.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *
 *  Swap reorganised 29.12.95,
 *  Asynchronous swapping added 30.12.95. Stephen Tweedie
 *  Removed race in async swapping. 14.4.1996. Bruno Haible
 *  Add swap of shared pages through the page cache. 20.2.1998. Stephen Tweedie
 *  Always use brw_page, life becomes simpler. 12 May 1998 Eric Biederman
 */

/*
 * Official Linux v6.0: mm/page_io.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/page_io.c#L335
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

int __swap_writepage(struct page *page, struct writeback_control *wbc,
		     bio_end_io_t end_write_func)
{
	struct bio *bio;
	int ret;
	struct swap_info_struct *sis = page_swap_info(page);

	VM_BUG_ON_PAGE(!PageSwapCache(page), page);
	/*
	 * ->flags can be updated non-atomicially (scan_swap_map_slots),
	 * but that will never affect SWP_FS_OPS, so the data_race
	 * is safe.
	 */
	if (data_race(sis->flags & SWP_FS_OPS))
		return swap_writepage_fs(page, wbc);

	ret = bdev_write_page(sis->bdev, swap_page_sector(page), page, wbc);
	if (!ret) {
		count_swpout_vm_event(page);
		return 0;
	}

	bio = bio_alloc(sis->bdev, 1,
			REQ_OP_WRITE | REQ_SWAP | wbc_to_write_flags(wbc),
			GFP_NOIO);
	bio->bi_iter.bi_sector = swap_page_sector(page);
	bio->bi_end_io = end_write_func;
	bio_add_page(bio, page, thp_size(page), 0);

	bio_associate_blkg_from_page(bio, page);
	count_swpout_vm_event(page);
	set_page_writeback(page);
	unlock_page(page);
	submit_bio(bio);

	return 0;
}
// SPDX-License-Identifier: GPL-2.0
/*
 *  linux/mm/page_io.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *
 *  Swap reorganised 29.12.95,
 *  Asynchronous swapping added 30.12.95. Stephen Tweedie
 *  Removed race in async swapping. 14.4.1996. Bruno Haible
 *  Add swap of shared pages through the page cache. 20.2.1998. Stephen Tweedie
 *  Always use brw_page, life becomes simpler. 12 May 1998 Eric Biederman
 */

/*
 * Official Linux v6.0: mm/page_io.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/page_io.c#L31
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

void end_swap_bio_write(struct bio *bio)
{
	struct page *page = bio_first_page_all(bio);

	if (bio->bi_status) {
		SetPageError(page);
		/*
		 * We failed to write the page out to swap-space.
		 * Re-dirty the page in order to avoid it being reclaimed.
		 * Also print a dire warning that things will go BAD (tm)
		 * very quickly.
		 *
		 * Also clear PG_reclaim to avoid folio_rotate_reclaimable()
		 */
		set_page_dirty(page);
		pr_alert_ratelimited("Write-error on swap-device (%u:%u:%llu)\n",
				     MAJOR(bio_dev(bio)), MINOR(bio_dev(bio)),
				     (unsigned long long)bio->bi_iter.bi_sector);
		ClearPageReclaim(page);
	}
	end_page_writeback(page);
	bio_put(bio);
}
이 tag의 swap_writepage()은 불필요해진 cache를 제거할 수 있으면 unlock하고 write를 생략합니다. architecture metadata 준비 실패는 redirty하고 종료하며, frontswap 저장 성공은 일반 block write 대신 해당 backend에서 writeback을 마칩니다. filesystem-mediated 경로와 bdev_write_page() 성공 경로도 bio 직접 제출과 별개입니다.
bio 경로는 sector·callback·page 범위·block-cgroup 연결을 정한 뒤 writeback을 시작하고 page를 unlock하여 제출합니다. write completion 오류는 error와 dirty를 설정하고 reclaim 표시를 지워 잘못된 eviction을 막습니다. 성공·실패 모두 writeback을 끝내고 bio reference를 반환합니다. 완료 뒤 회수 순서에 가까워질 수는 있어도 callback이 folio를 allocator에 직접 반환하는 것은 아닙니다.
Freeze는 dirty 검사보다 앞에 있어야 합니다
아래 v6.0 __remove_mapping()은 기대한 count를 0으로 freeze한 뒤 dirty를 검사합니다. 반대로 dirty를 먼저 보고 나중에 count만 확인하면, 중간에 reference를 얻은 writer가 수정·dirty 설정·put을 끝내 count만 원래대로 돌아오는 경쟁을 놓칠 수 있습니다. atomic freeze의 ordering과 뒤의 dirty 관찰이 함께 필요합니다.
// SPDX-License-Identifier: GPL-2.0
/*
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *
 *  Swap reorganised 29.12.95, Stephen Tweedie.
 *  kswapd added: 7.1.96  sct
 *  Removed kswapd_ctl limits, and swap out as many pages as needed
 *  to bring the system back to freepages.high: 2.4.97, Rik van Riel.
 *  Zone aware kswapd started 02/00, Kanoj Sarcar (kanoj@sgi.com).
 *  Multiqueue VM started 5.8.00, Rik van Riel.
 */

#define pr_fmt(fmt) KBUILD_MODNAME ": " fmt

/*
 * Official Linux v6.0: mm/vmscan.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/vmscan.c#L1289
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

static int __remove_mapping(struct address_space *mapping, struct folio *folio,
			    bool reclaimed, struct mem_cgroup *target_memcg)
{
	int refcount;
	void *shadow = NULL;

	BUG_ON(!folio_test_locked(folio));
	BUG_ON(mapping != folio_mapping(folio));

	if (!folio_test_swapcache(folio))
		spin_lock(&mapping->host->i_lock);
	xa_lock_irq(&mapping->i_pages);
	/*
	 * The non racy check for a busy page.
	 *
	 * Must be careful with the order of the tests. When someone has
	 * a ref to the page, it may be possible that they dirty it then
	 * drop the reference. So if PageDirty is tested before page_count
	 * here, then the following race may occur:
	 *
	 * get_user_pages(&page);
	 * [user mapping goes away]
	 * write_to(page);
	 *				!PageDirty(page)    [good]
	 * SetPageDirty(page);
	 * put_page(page);
	 *				!page_count(page)   [good, discard it]
	 *
	 * [oops, our write_to data is lost]
	 *
	 * Reversing the order of the tests ensures such a situation cannot
	 * escape unnoticed. The smp_rmb is needed to ensure the page->flags
	 * load is not satisfied before that of page->_refcount.
	 *
	 * Note that if SetPageDirty is always performed via set_page_dirty,
	 * and thus under the i_pages lock, then this ordering is not required.
	 */
	refcount = 1 + folio_nr_pages(folio);
	if (!folio_ref_freeze(folio, refcount))
		goto cannot_free;
	/* note: atomic_cmpxchg in page_ref_freeze provides the smp_rmb */
	if (unlikely(folio_test_dirty(folio))) {
		folio_ref_unfreeze(folio, refcount);
		goto cannot_free;
	}

	if (folio_test_swapcache(folio)) {
		swp_entry_t swap = folio_swap_entry(folio);
		mem_cgroup_swapout(folio, swap);
		if (reclaimed && !mapping_exiting(mapping))
			shadow = workingset_eviction(folio, target_memcg);
		__delete_from_swap_cache(folio, swap, shadow);
		xa_unlock_irq(&mapping->i_pages);
		put_swap_page(&folio->page, swap);
	} else {
		void (*free_folio)(struct folio *);

		free_folio = mapping->a_ops->free_folio;
		/*
		 * Remember a shadow entry for reclaimed file cache in
		 * order to detect refaults, thus thrashing, later on.
		 *
		 * But don't store shadows in an address space that is
		 * already exiting.  This is not just an optimization,
		 * inode reclaim needs to empty out the radix tree or
		 * the nodes are lost.  Don't plant shadows behind its
		 * back.
		 *
		 * We also don't store shadows for DAX mappings because the
		 * only page cache pages found in these are zero pages
		 * covering holes, and because we don't want to mix DAX
		 * exceptional entries and shadow exceptional entries in the
		 * same address_space.
		 */
		if (reclaimed && folio_is_file_lru(folio) &&
		    !mapping_exiting(mapping) && !dax_mapping(mapping))
			shadow = workingset_eviction(folio, target_memcg);
		__filemap_remove_folio(folio, shadow);
		xa_unlock_irq(&mapping->i_pages);
		if (mapping_shrinkable(mapping))
			inode_add_lru(mapping->host);
		spin_unlock(&mapping->host->i_lock);

		if (free_folio)
			free_folio(folio);
	}

	return 1;

cannot_free:
	xa_unlock_irq(&mapping->i_pages);
	if (!folio_test_swapcache(folio))
		spin_unlock(&mapping->host->i_lock);
	return 0;
}
v6_0__delete_from_swap_cache.c
// SPDX-License-Identifier: GPL-2.0
/*
 *  linux/mm/swap_state.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 *
 *  Rewritten to use page cache, (C) 1998 Stephen Tweedie
 */

/*
 * Official Linux v6.0: mm/swap_state.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/swap_state.c#L139
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

void __delete_from_swap_cache(struct folio *folio,
			swp_entry_t entry, void *shadow)
{
	struct address_space *address_space = swap_address_space(entry);
	int i;
	long nr = folio_nr_pages(folio);
	pgoff_t idx = swp_offset(entry);
	XA_STATE(xas, &address_space->i_pages, idx);

	VM_BUG_ON_FOLIO(!folio_test_locked(folio), folio);
	VM_BUG_ON_FOLIO(!folio_test_swapcache(folio), folio);
	VM_BUG_ON_FOLIO(folio_test_writeback(folio), folio);

	for (i = 0; i < nr; i++) {
		void *entry = xas_store(&xas, shadow);
		VM_BUG_ON_PAGE(entry != folio, entry);
		set_page_private(folio_page(folio, i), 0);
		xas_next(&xas);
	}
	folio_clear_swapcache(folio);
	address_space->nrpages -= nr;
	__node_stat_mod_folio(folio, NR_FILE_PAGES, -nr);
	__lruvec_stat_mod_folio(folio, NR_SWAPCACHE, -nr);
}
// SPDX-License-Identifier: GPL-2.0
/*
 *  linux/mm/swap_state.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 *
 *  Rewritten to use page cache, (C) 1998 Stephen Tweedie
 */

/*
 * Official Linux v6.0: mm/swap_state.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/swap_state.c#L231
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

void delete_from_swap_cache(struct folio *folio)
{
	swp_entry_t entry = folio_swap_entry(folio);
	struct address_space *address_space = swap_address_space(entry);

	xa_lock_irq(&address_space->i_pages);
	__delete_from_swap_cache(folio, entry, NULL);
	xa_unlock_irq(&address_space->i_pages);

	put_swap_page(&folio->page, entry);
	folio_ref_sub(folio, folio_nr_pages(folio));
}
low-level 삭제는 각 XArray index를 shadow 또는 빈 값으로 바꾸고 private entry·cache flag·통계를 정리합니다. 이 함수 자체가 cache-held folio reference를 무조건 put하는 것은 아닙니다. 이미 freeze한 reclaim caller와, 별도 reference를 보유한 delete_from_swap_cache() wrapper가 각자의 reference protocol을 마무리합니다. wrapper는 cache-held base-page 수만큼 count를 줄이지만 caller가 가진 reference 때문에 이 호출만으로 final free하지 않습니다.
Cache를 버릴 수 있는 조건을 끝까지 검사합니다
v6.0 try_to_free_swap()의 성공은 swap cache이며 writeback 중이 아니고 folio_swapped()가 false이며 hibernation storage 보호에 막히지 않을 때입니다. '참조가 하나 이상 있으므로 free한다'는 반대 해석은 맞지 않습니다. 여기서 남은 swap reference와 resident folio reference는 다른 수입니다.
// SPDX-License-Identifier: GPL-2.0-only
/*
 *  linux/mm/swapfile.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 */

/*
 * Official Linux v6.0: mm/swapfile.c
 * https://github.com/torvalds/linux/blob/v6.0/mm/swapfile.c#L1590
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

int try_to_free_swap(struct page *page)
{
	struct folio *folio = page_folio(page);
	VM_BUG_ON_FOLIO(!folio_test_locked(folio), folio);

	if (!folio_test_swapcache(folio))
		return 0;
	if (folio_test_writeback(folio))
		return 0;
	if (folio_swapped(folio))
		return 0;

	/*
	 * Once hibernation has begun to create its image of memory,
	 * there's a danger that one of the calls to try_to_free_swap()
	 * - most probably a call from __try_to_reclaim_swap() while
	 * hibernation is allocating its own swap pages for the image,
	 * but conceivably even a call from memory reclaim - will free
	 * the swap from a page which has already been recorded in the
	 * image as a clean swapcache page, and then reuse its swap for
	 * another page of the image.  On waking from hibernation, the
	 * original page might be freed under memory pressure, then
	 * later read back in from swap, now with the wrong data.
	 *
	 * Hibernation suspends storage while it is writing the image
	 * to disk so check that here.
	 */
	if (pm_suspended_storage())
		return 0;

	delete_from_swap_cache(folio);
	folio_set_dirty(folio);
	return 1;
}
v6_12_folio_swapcache_freeable.c
// SPDX-License-Identifier: GPL-2.0-only
/*
 *  linux/mm/swapfile.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 */

/*
 * Official Linux v6.12: mm/swapfile.c
 * https://github.com/torvalds/linux/blob/v6.12/mm/swapfile.c#L1830
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

static bool folio_swapcache_freeable(struct folio *folio)
{
	VM_BUG_ON_FOLIO(!folio_test_locked(folio), folio);

	if (!folio_test_swapcache(folio))
		return false;
	if (folio_test_writeback(folio))
		return false;

	/*
	 * Once hibernation has begun to create its image of memory,
	 * there's a danger that one of the calls to folio_free_swap()
	 * - most probably a call from __try_to_reclaim_swap() while
	 * hibernation is allocating its own swap pages for the image,
	 * but conceivably even a call from memory reclaim - will free
	 * the swap from a folio which has already been recorded in the
	 * image as a clean swapcache folio, and then reuse its swap for
	 * another page of the image.  On waking from hibernation, the
	 * original folio might be freed under memory pressure, then
	 * later read back in from swap, now with the wrong data.
	 *
	 * Hibernation suspends storage while it is writing the image
	 * to disk so check that here.
	 */
	if (pm_suspended_storage())
		return false;

	return true;
}
// SPDX-License-Identifier: GPL-2.0-only
/*
 *  linux/mm/swapfile.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 *  Swap reorganised 29.12.95, Stephen Tweedie
 */

/*
 * Official Linux v6.12: mm/swapfile.c
 * https://github.com/torvalds/linux/blob/v6.12/mm/swapfile.c#L1869
 * Exact definition/declaration; not a reconstruction of a book listing.
 * See GPL-2.0.txt. Not a standalone translation unit.
 */

bool folio_free_swap(struct folio *folio)
{
	if (!folio_swapcache_freeable(folio))
		return false;
	if (folio_swapped(folio))
		return false;

	delete_from_swap_cache(folio);
	folio_set_dirty(folio);
	return true;
}
v6.12는 공통 freeable 검사를 별도 helper로 분리합니다. hibernation이 clean swapcache의 slot을 image에 기록해 둔 뒤 이를 다른 내용에 재사용하면 복귀 후 잘못된 내용을 읽을 수 있어 storage-suspended 상태를 제한합니다. 조건을 통과한 cache 제거 후에는 RAM 내용의 보존 책임이 계속되므로 dirty로 남깁니다.
참고 자료
- Lorenzo Stoakes, The Linux Memory Manager, Early Access 2025, Chapter 12, Swapping Out.
- Linux v6.12 mm/swap_state.c: cache 추가·삭제.
- Linux v6.12 mm/swapfile.c:
folio_free_swap()과 slot accounting. - Linux v6.12 mm/page_io.c: swap backend와 completion.
- Linux v6.12 mm/vmscan.c, mm/swap_slots.c.