같은 file page를 열 개 process가 mapping하면 RSS를 모두 더한 값이 실제 data page 열 장을 뜻할까요? 그렇지 않습니다. RSS는 각 address space가 resident하게 mapping한 양을 세며, shared physical page를 process별로 다시 셀 수 있습니다. memory 사용량을 읽을 때는 counter의 분류뿐 아니라 공유와 집계 방식도 알아야 합니다.
또한 빠른 counter가 page-table 순회와 항상 같은 값을 내는 것도 아닙니다. 이 글은 upstream v6.18의 counter 구현을 기준으로, 예전 per-thread batching과의 차이를 구분합니다. 통계의 정확도를 '늘 정확함'과 '쓸모없음' 두 가지로 나누지 않고 무엇을 저렴하게 관측하는지 살펴보겠습니다.
네 counter는 같은 합계에 들어가지 않습니다
MM_ANONPAGES는 resident anonymous page를, MM_FILEPAGES는 shmem을 제외한 resident file page를, MM_SHMEMPAGES는 resident shmem-backed page를 셉니다. MM_SWAPENTS는 swap entry 관련 양입니다. swap에 있는 page를 resident RSS에 그대로 더해서는 안 됩니다.
v6.18 get_mm_rss()는 앞의 세 resident counter를 더합니다. 일반적으로 kernel 내부 count는 base-page 단위이고 procfs 출력에서는 byte나 kB로 변환합니다. huge folio 한 개와 base page 한 장을 무조건 같은 1로 세는 개수표가 아닙니다.
VMA의 종류와 counter 분류가 항상 일치하는 것도 아닙니다. private file VMA에서 CoW가 발생하면 그 PTE가 가리키는 data는 anonymous가 될 수 있습니다. mapping의 pathname이 남아 있다고 해서 모든 page가 계속 MM_FILEPAGES에 들어가는 것은 아닙니다. current mm_counter()와 mm_counter_file()은 folio의 anonymous 및 swap-backed 성질을 보고 resident 분류를 선택합니다.
swap entry의 수 또한 현재 system swap storage의 unique 사용량과 같지 않습니다. fork와 공유 관계, swap cache 등 별도 상태가 있기 때문입니다. 특정 mm의 통계와 system 전체 물리 자원 통계를 분리해서 읽어야 합니다.
virtual size와 page table 비용도 따로 셉니다
아직 접근하지 않은 넓은 anonymous VMA는 virtual size를 늘리지만 같은 크기의 RSS를 만들지 않을 수 있습니다. commit accounting은 미래 writable backing의 부담을 admission 단계에서 반영하므로, 지금 resident page가 늘지 않아도 변할 수 있습니다. RSS가 작다고 commitment도 반드시 작지는 않습니다.
page table 자체도 RAM을 사용합니다. sparse 주소를 멀리 떨어뜨려 조금씩 접근하면 data 양에 비해 table 비용이 커질 수 있습니다. 그러나 mm의 data RSS와 pgtables_bytes는 같은 항목이 아닙니다. map_count 역시 VMA 개수이지 mapped page 수가 아닙니다. 숫자가 모두 mm에 들어 있다고 해서 하나의 memory 사용량 합계로 더해서는 안 됩니다.
shared zero page나 special PFN mapping도 ordinary resident folio accounting과 똑같이 해석할 수 없습니다. hardware가 어떤 translation을 가진다는 사실만으로 그만큼의 새 private RAM을 해당 process가 소유한다고 말할 수 없는 이유입니다.
예전 batching은 task별로 미뤘습니다
historical SPLIT_RSS_COUNTING 구현에서는 task_struct의 task_rss_stat에 local delta와 event 수를 두고, mm의 atomic counter로 주기적으로 합쳤습니다. 같은 mm을 쓰는 여러 thread가 매 page마다 하나의 shared atomic cache line을 갱신하는 비용을 줄이기 위한 방식입니다.
current task의 mm에 대한 빠른 update는 task-local delta를 바꾸고, 다른 mm에 대한 update 등은 공통 counter 쪽 경로를 사용할 수 있었습니다. check_sync_rss_stat()는 fault 경로에서 event를 확인하고 threshold를 넘으면 sync_mm_rss()로 delta를 반영합니다. 후자는 각 counter의 local 값을 shared 값에 더한 뒤 local 상태를 비웁니다.
구체적인 historical 기준인 v5.18 mm/memory.c는 TASK_RSS_EVENTS_THRESH를 64로 정의합니다. 다만 주석의 '64 faults마다'를 모든 증가가 정확히 64번째에 동기화된다는 기계적 약속으로 바꾸지 않는 편이 좋습니다. 실제 조건은 post-increment와 > 비교이고, 모든 update 경로가 같은 event check를 통과하는 것도 아닙니다.
task별 미반영 delta가 많으면 thread가 많은 process의 빠른 aggregate가 실제 상태에서 더 멀어질 수 있습니다. 그렇다고 그 과거 오차 모델을 현재 버전에 그대로 적용하면 안 됩니다. 알고리즘과 counter 위치가 바뀌었기 때문입니다.
이 방식은 official v6.0 mm_types_task.h와 memory.c에서도 확인할 수 있습니다. 다음은 그 tag의 전체 구조체와 전체 함수입니다. kernel 내부 의존성이 있는 GPL code이며 configuration의 SPLIT_RSS_COUNTING 분기를 대상으로 합니다. 책의 정확한 source revision을 이 tag로 단정하는 것은 아닙니다.
/* SPDX-License-Identifier: GPL-2.0 */
/*
 * Official Linux v6.0: include/linux/mm_types_task.h
 * Complete struct; source lines 54-57.
 * Body unchanged. Kernel dependencies and configuration are required.
 * Source URL, SHA, commit, and license: provenance.json; GPL-2.0.txt.
 */

struct task_rss_stat {
	int events;	/* for synchronization threshold */
	int count[NR_MM_COUNTERS];
};
/* SPDX-License-Identifier: GPL-2.0 */
/*
 * Official Linux v6.0: include/linux/mm_types_task.h
 * Complete struct; source lines 60-62.
 * Body unchanged. Kernel dependencies and configuration are required.
 * Source URL, SHA, commit, and license: provenance.json; GPL-2.0.txt.
 */

struct mm_rss_stat {
	atomic_long_t count[NR_MM_COUNTERS];
};
// SPDX-License-Identifier: GPL-2.0-only
/*
 *  linux/mm/memory.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 */

/*
 * demand-loading started 01.12.91 - seems it is high on the list of
 * things wanted, and it should be easy to implement. - Linus
 */

/*
 * Ok, demand-loading was easy, shared pages a little bit tricker. Shared
 * pages started 02.12.91, seems to work. - Linus.
 *
 * Tested sharing by executing about 30 /bin/sh: under the old kernel it
 * would have taken more than the 6M I have free, but it worked well as
 * far as I could see.
 *
 * Also corrected some "invalidate()"s - I wasn't doing enough of them.
 */

/*
 * Real VM (paging to/from disk) started 18.12.91. Much more work and
 * thought has to go into this. Oh, well..
 * 19.12.91  -  works, somewhat. Sometimes I get faults, don't know why.
 *		Found it. Everything seems to work now.
 * 20.12.91  -  Ok, making the swap-device changeable like the root.
 */

/*
 * 05.04.94  -  Multi-page memory management added for v1.1.
 *              Idea by Alex Bligh (alex@cconcepts.co.uk)
 *
 * 16.07.99  -  Support of BIGMEM added by Gerhard Wichert, Siemens AG
 *		(Gerhard.Wichert@pdb.siemens.de)
 *
 * Aug/Sep 2004 Changed to four level page tables (Andi Kleen)
 */
/*
 * Official Linux v6.0: mm/memory.c
 * Complete function; source lines 194-202.
 * Body unchanged. Kernel dependencies and configuration are required.
 * Source URL, SHA, commit, and license: provenance.json; GPL-2.0.txt.
 */

static void add_mm_counter_fast(struct mm_struct *mm, int member, int val)
{
	struct task_struct *task = current;

	if (likely(task->mm == mm))
		task->rss_stat.count[member] += val;
	else
		add_mm_counter(mm, member, val);
}
// SPDX-License-Identifier: GPL-2.0-only
/*
 *  linux/mm/memory.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 */

/*
 * demand-loading started 01.12.91 - seems it is high on the list of
 * things wanted, and it should be easy to implement. - Linus
 */

/*
 * Ok, demand-loading was easy, shared pages a little bit tricker. Shared
 * pages started 02.12.91, seems to work. - Linus.
 *
 * Tested sharing by executing about 30 /bin/sh: under the old kernel it
 * would have taken more than the 6M I have free, but it worked well as
 * far as I could see.
 *
 * Also corrected some "invalidate()"s - I wasn't doing enough of them.
 */

/*
 * Real VM (paging to/from disk) started 18.12.91. Much more work and
 * thought has to go into this. Oh, well..
 * 19.12.91  -  works, somewhat. Sometimes I get faults, don't know why.
 *		Found it. Everything seems to work now.
 * 20.12.91  -  Ok, making the swap-device changeable like the root.
 */

/*
 * 05.04.94  -  Multi-page memory management added for v1.1.
 *              Idea by Alex Bligh (alex@cconcepts.co.uk)
 *
 * 16.07.99  -  Support of BIGMEM added by Gerhard Wichert, Siemens AG
 *		(Gerhard.Wichert@pdb.siemens.de)
 *
 * Aug/Sep 2004 Changed to four level page tables (Andi Kleen)
 */
/*
 * Official Linux v6.0: mm/memory.c
 * Complete function; source lines 208-214.
 * Body unchanged. Kernel dependencies and configuration are required.
 * Source URL, SHA, commit, and license: provenance.json; GPL-2.0.txt.
 */

static void check_sync_rss_stat(struct task_struct *task)
{
	if (unlikely(task != current))
		return;
	if (unlikely(task->rss_stat.events++ > TASK_RSS_EVENTS_THRESH))
		sync_mm_rss(task->mm);
}
// SPDX-License-Identifier: GPL-2.0-only
/*
 *  linux/mm/memory.c
 *
 *  Copyright (C) 1991, 1992, 1993, 1994  Linus Torvalds
 */

/*
 * demand-loading started 01.12.91 - seems it is high on the list of
 * things wanted, and it should be easy to implement. - Linus
 */

/*
 * Ok, demand-loading was easy, shared pages a little bit tricker. Shared
 * pages started 02.12.91, seems to work. - Linus.
 *
 * Tested sharing by executing about 30 /bin/sh: under the old kernel it
 * would have taken more than the 6M I have free, but it worked well as
 * far as I could see.
 *
 * Also corrected some "invalidate()"s - I wasn't doing enough of them.
 */

/*
 * Real VM (paging to/from disk) started 18.12.91. Much more work and
 * thought has to go into this. Oh, well..
 * 19.12.91  -  works, somewhat. Sometimes I get faults, don't know why.
 *		Found it. Everything seems to work now.
 * 20.12.91  -  Ok, making the swap-device changeable like the root.
 */

/*
 * 05.04.94  -  Multi-page memory management added for v1.1.
 *              Idea by Alex Bligh (alex@cconcepts.co.uk)
 *
 * 16.07.99  -  Support of BIGMEM added by Gerhard Wichert, Siemens AG
 *		(Gerhard.Wichert@pdb.siemens.de)
 *
 * Aug/Sep 2004 Changed to four level page tables (Andi Kleen)
 */
/*
 * Official Linux v6.0: mm/memory.c
 * Complete function; source lines 181-192.
 * Body unchanged. Kernel dependencies and configuration are required.
 * Source URL, SHA, commit, and license: provenance.json; GPL-2.0.txt.
 */

void sync_mm_rss(struct mm_struct *mm)
{
	int i;

	for (i = 0; i < NR_MM_COUNTERS; i++) {
		if (current->rss_stat.count[i]) {
			add_mm_counter(mm, i, current->rss_stat.count[i]);
			current->rss_stat.count[i] = 0;
		}
	}
	current->rss_stat.events = 0;
}
event를 0부터 시작해 이 검사만 반복한다면 1번째 검사에서는 비교에 0을 쓰고 65번째에서는 64를 씁니다. 66번째에서 비교값 65가 64보다 커져 sync하고 event를 0으로 되돌립니다. 그런데 event 검사 횟수와 RSS page delta는 같은 수가 아닙니다. 한 경로에서 여러 page를 갱신하거나 다른 API로 RSS를 변경할 수 있으므로, 이 조건식으로 미반영 RSS의 절대 상한을 64 page라고 증명할 수는 없습니다.
v6.18은 per-CPU counter를 사용합니다
전환 시점을 고정된 tag로 비교할 수도 있습니다. v6.1의 mm_struct는 struct mm_rss_stat를 보유하지만, v6.2의 정의는 struct percpu_counter rss_stat[NR_MM_COUNTERS]를 사용합니다. 이 변화 때문에 historical task별 threshold를 이후 kernel의 오차 공식으로 옮기지 않아야 합니다.
현재 mm_struct.rss_stat은 struct percpu_counter 배열입니다. add_mm_counter(), inc_mm_counter(), dec_mm_counter()는 이 counter API로 update합니다. 예전 task_rss_stat 배열을 매 task에서 flush하는 그림은 v6.18의 layout이 아닙니다.
per-CPU counter는 CPU-local 누적과 공통 합계 사이에서 비용과 관측 정확도를 조절합니다. 자주 읽는 값은 모든 CPU의 최신 local contribution을 매번 완전히 합산한 snapshot과 다를 수 있습니다. counter API에 read와 sum 계열이 따로 있는 이유입니다. 정확한 편차는 사용 helper, batching과 CPU 수 및 동시 update 등에 의존하므로 '현재도 최대 64 page 곱하기 thread 수'라는 과거 공식을 적용하지 않습니다.
mm 생성 시에는 이 counter들의 초기화도 allocation 실패 지점입니다. teardown에서는 counter 자원을 반환해야 합니다. 통계를 위한 metadata도 수명을 갖는다는 점에서, 단순한 정적 정수 몇 개로만 취급할 수 없습니다.
RSS 증가가 반드시 handle_mm_fault() 한 곳에서만 일어나는 것도 아닙니다. v6.18 insert_page_into_pte_locked()는 일반 page insertion 시 inc_mm_counter()를 호출합니다. 그러므로 vm_insert_pages()는 RSS를 전혀 갱신하지 않는다는 설명을 현행 구현에 적용하면 틀립니다. ordinary page와 special zero folio의 분기, insertion 성공 여부를 구별해서 보아야 합니다.
current helper도 전체를 나란히 보면 차이가 선명합니다. v6.18 mm.h의 빠른 read와 sum, update, resident 합계입니다.
/* SPDX-License-Identifier: GPL-2.0 */
/*
 * Official Linux v6.18: include/linux/mm.h
 * Complete function; source lines 2687-2690.
 * Body unchanged. Kernel dependencies and configuration are required.
 * Source URL, SHA, commit, and license: provenance.json; GPL-2.0.txt.
 */

static inline unsigned long get_mm_counter(struct mm_struct *mm, int member)
{
	return percpu_counter_read_positive(&mm->rss_stat[member]);
}
/* SPDX-License-Identifier: GPL-2.0 */
/*
 * Official Linux v6.18: include/linux/mm.h
 * Complete function; source lines 2692-2695.
 * Body unchanged. Kernel dependencies and configuration are required.
 * Source URL, SHA, commit, and license: provenance.json; GPL-2.0.txt.
 */

static inline unsigned long get_mm_counter_sum(struct mm_struct *mm, int member)
{
	return percpu_counter_sum_positive(&mm->rss_stat[member]);
}
/* SPDX-License-Identifier: GPL-2.0 */
/*
 * Official Linux v6.18: include/linux/mm.h
 * Complete function; source lines 2699-2704.
 * Body unchanged. Kernel dependencies and configuration are required.
 * Source URL, SHA, commit, and license: provenance.json; GPL-2.0.txt.
 */

static inline void add_mm_counter(struct mm_struct *mm, int member, long value)
{
	percpu_counter_add(&mm->rss_stat[member], value);

	mm_trace_rss_stat(mm, member);
}
/* SPDX-License-Identifier: GPL-2.0 */
/*
 * Official Linux v6.18: include/linux/mm.h
 * Complete function; source lines 2735-2740.
 * Body unchanged. Kernel dependencies and configuration are required.
 * Source URL, SHA, commit, and license: provenance.json; GPL-2.0.txt.
 */

static inline unsigned long get_mm_rss(struct mm_struct *mm)
{
	return get_mm_counter(mm, MM_FILEPAGES) +
		get_mm_counter(mm, MM_ANONPAGES) +
		get_mm_counter(mm, MM_SHMEMPAGES);
}
sum은 local contribution을 모으는 비용을 지불하지만, 여러 counter를 서로 다른 시점에 읽는 전체 프로그램을 자동으로 하나의 원자적인 snapshot으로 만들지는 않습니다. 과거 per-task delta와 현재 per-CPU delta의 오차를 같은 공식으로 묶지 않아야 합니다.
RSS와 PSS는 다른 질문에 답합니다
단순화를 위해 4 KiB ordinary file page 한 장만 A와 B가 각각 한 번 mapping하고, 다른 이용자와 alias가 없다고 가정하겠습니다. A의 RSS와 B의 RSS에는 각각 4 KiB가 들어갈 수 있습니다. 두 RSS의 합은 8 KiB이지만 data page의 physical 보관량은 한 장입니다.
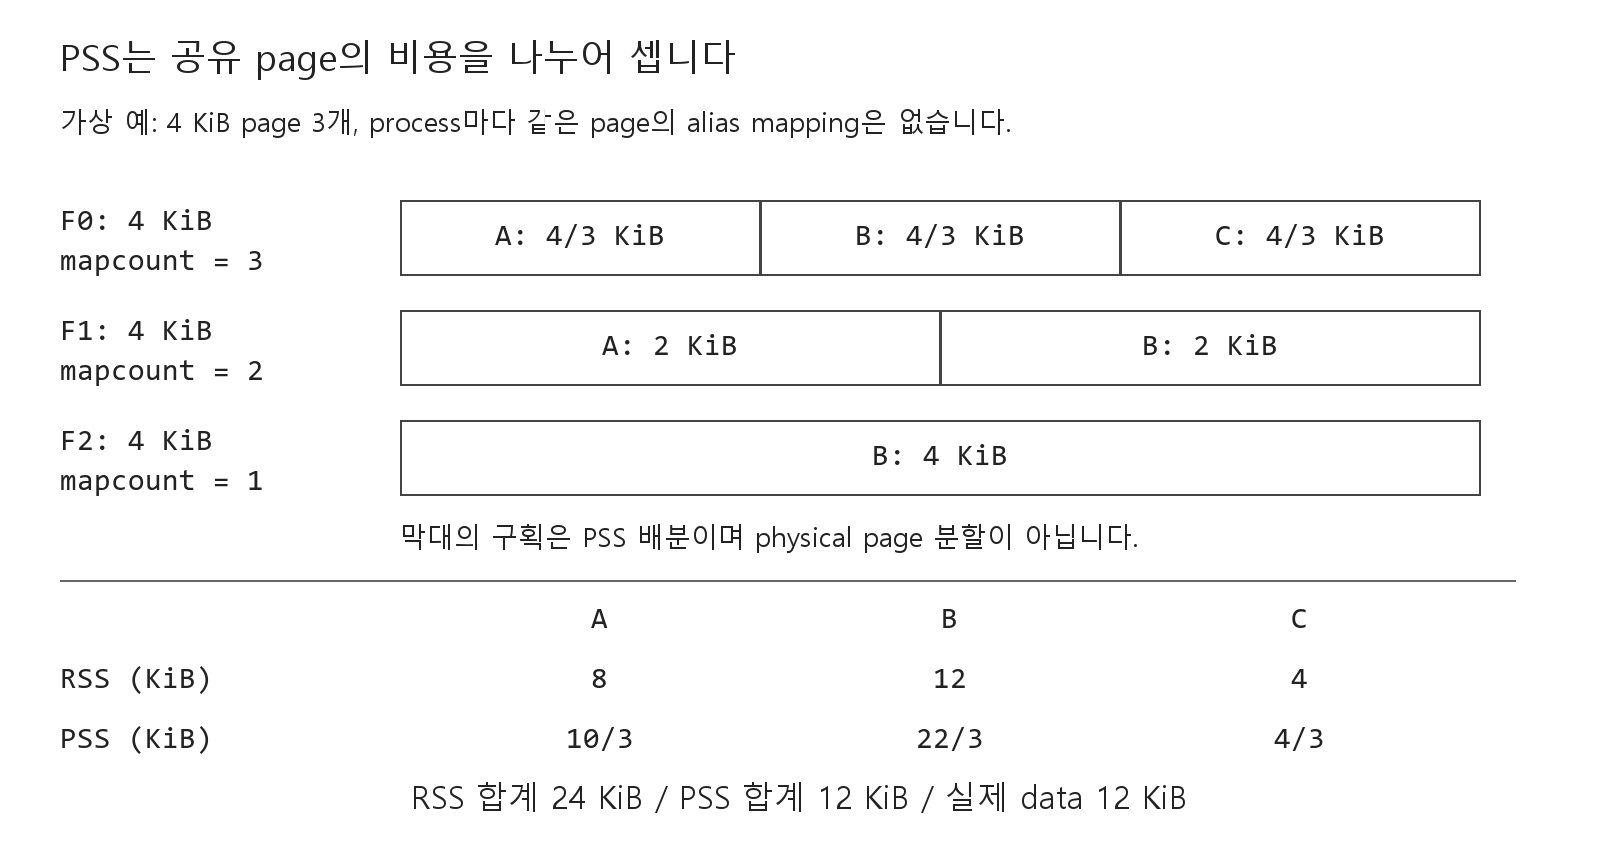
그림은 앞의 한-page 예제와 달리 세 process가 세 ordinary page를 서로 다르게 공유하는 예입니다. huge folio, KSM, alias와 동시 unmap은 생략했습니다.
이 조건에서 PSS는 공유분을 나누어 각자 약 2 KiB를 반영합니다. A가 private write로 독립 anonymous page를 만들었다면 A는 자기 page를, B는 남은 file page를 가리키게 되어 공유 관계가 달라집니다. 두 process의 RSS가 그대로여도 unique physical data 양은 늘 수 있습니다.
실제 PSS는 page/folio의 공유 상태를 조사하고 fixed-point 계산으로 누적합니다. 'file을 연 process 개수로 file 크기를 나누면 PSS'라는 공식은 아닙니다. cache에만 있는 page는 해당 process RSS가 아니며, VMA range에 있어도 present하지 않은 부분은 resident data가 아닙니다.
정밀한 관측에도 시간 경계가 있습니다
/proc/PID/status나 statm의 빠른 aggregate는 비용이 낮지만 batching 등의 이유로 정밀한 현재값과 차이가 날 수 있습니다. smaps와 smaps_rollup은 mapping과 page table을 조사하여 더 자세한 resident 및 proportional 상태를 구합니다. 전자는 range별로, 후자는 process 전체의 rollup으로 읽기 좋습니다.
그러나 page-table 순회도 모든 CPU와 process를 영구적으로 멈춘 완벽한 system-wide snapshot은 아닙니다. 읽는 동안 다른 thread가 page를 fault하거나 unmap할 수 있고, 여러 process를 차례로 읽으면 관측 시점도 다릅니다. 더 자세한 통계와 시간적으로 원자적인 전체 상태를 같은 말로 부르면 안 됩니다.
어떤 수치가 필요한지 먼저 정하면 선택이 쉬워집니다. 주소 공간이 커졌는지는 VMA 길이와 virtual size, resident 분류는 RSS, shared 부담의 배분은 PSS, 미래 backing의 admission 부담은 commit을 봅니다. 그 다음 사용하는 kernel의 counter 구현과 관측 인터페이스를 확인하면, 서로 다른 수치가 다른 방향으로 움직이는 상황도 설명할 수 있습니다.
참고 자료
- Lorenzo Stoakes, The Linux Memory Manager, Early Access 2025, Chapter 4의 per-process statistical counters 설명.
- Linux v5.18 memory.c: historical per-task RSS batching
- Linux v6.18 mm_types.h: 현재 per-CPU RSS storage
- Linux v6.18 mm.h: counter update와 get_mm_rss
- Linux v6.18 memory.c: page insertion accounting
- Linux v6.18 task_mmu.c: smaps와 PSS 계산
- Linux v6.18 percpu_counter.c: local 및 aggregate counter